
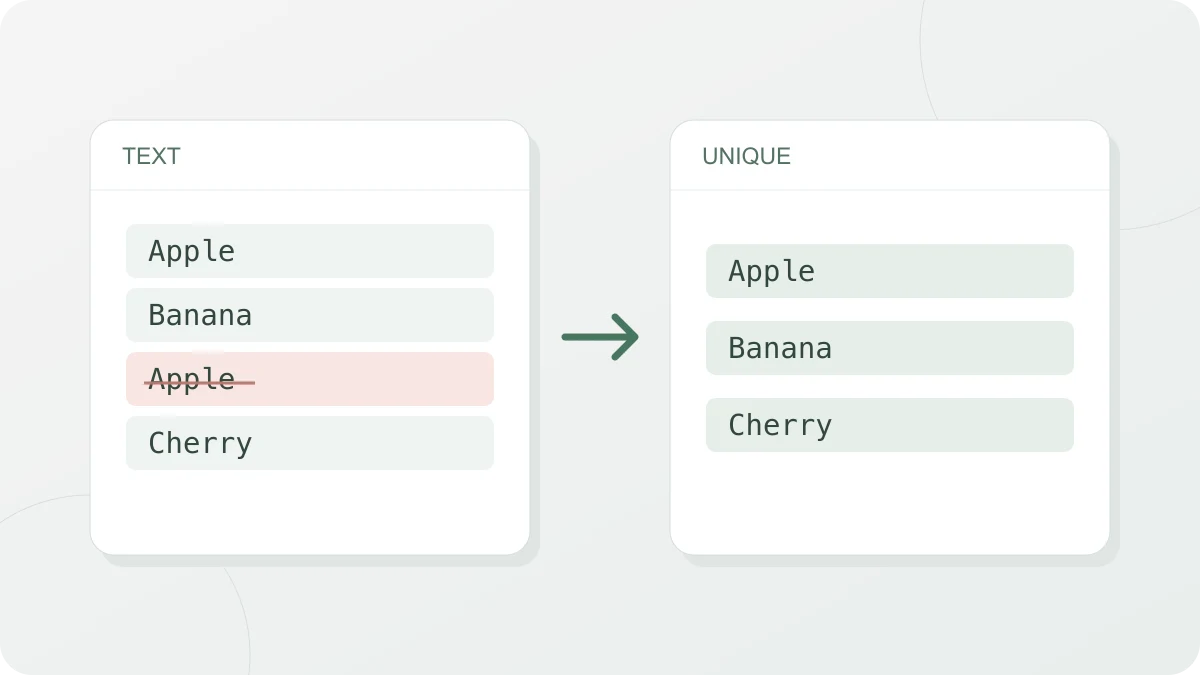
How to use
Paste one value per line into “Input”, and “Output” keeps only the first line for each value. The lines that remain stay in the order you entered them, and a message next to “Output” tells you how many went, for example “Removed 3 duplicate lines.” If nothing repeats, it says “No duplicate lines found.”
The options come in two groups. The three under “Compare by” decide which lines count as the same, and “Show removed lines only” under “Output” decides what the result shows.
What counts as the same line
With every option off, two lines match only if they are identical from the first character to the last. One extra space or one capital letter is enough to keep both. The “Compare by” options loosen that rule.
- Ignore case: treats
Apple,appleandAPPLEas one value and keeps whichever spelling came first. - Trim whitespace before comparing: strips spaces, tabs and full-width spaces from the start and end of each line before comparing. The stripping is for the comparison only, so a line that is kept still carries its whitespace in the result.
- Ignore empty lines: leaves empty lines out of both the comparison and the result.
One case is always treated as the same line, whatever the options. An accented Latin letter (é), a Japanese kana with a voicing mark (が) or a Korean Hangul syllable (가) can be stored as one complete character, or split into a base letter and a separate mark (for Hangul, a consonant and a vowel). File names created on macOS are often stored the second way. The two look exactly alike on screen, and the tool treats them as the same line.
How the options change the result
Here is what happens to the six lines below. The third line has one space before it and one after it.
hong@test.com
Kim@test.com
 hong@test.com
kim@test.com
lee@test.com
hong@test.com| Options on | Lines kept | Lines removed |
|---|---|---|
| None | 5 lines | 1 line (the sixth) |
| Ignore case | 4 lines | 2 lines (fourth, sixth) |
| Trim whitespace before comparing | 4 lines | 2 lines (third, sixth) |
| Both | 3 lines | 3 lines (third, fourth, sixth) |
With both options on, three lines are left: hong@test.com, Kim@test.com and lee@test.com. Kim@test.com appears before kim@test.com, so the capitalized spelling is the one that stays. You can’t choose which spelling to keep. It is always the earlier one.
Empty lines
With “Ignore empty lines” off, an empty line is a value like any other. If there are several, the first stays and the rest are removed as duplicates. If you paste text with an empty line between paragraphs, only the first gap survives and the later paragraphs run together, so this tool is the wrong fit for that kind of text.
“Ignore empty lines” only counts a line as empty when it has no characters at all. To drop lines that hold nothing but spaces or tabs as well, turn on “Trim whitespace before comparing” alongside it.
Showing only the removed lines
“Show removed lines only” flips the result. Instead of the lines that stay, you get the lines that would be removed, in the order you entered them. It is a way to check what you are about to lose before you rely on the cleaned list. A value that appears three times has its second and third copies removed, so it shows up twice here. The four lines a, b, a, a give the two lines a, a.
Lines that only partly match
The comparison always covers the whole line. In a table with columns separated by commas or tabs, the tool won’t find rows that share one particular column. 1,kim and 2,kim have the same name but are different lines, so both stay. To remove duplicates by name, copy just the name column and paste that in. Lists where one value spreads over several lines, such as postal addresses, don’t work either, because each line is compared on its own.